AI Transaction Monitoring for AML: How It Works, Where It Fails, and What Examiners Expect
Fintech Analyst · Founder of Tech Capital Hub
Marcus covers AI in financial crime compliance, payment risk, and fintech systems in plain English for operators, compliance teams, and curious readers. In this guide, he explains how AI transaction monitoring works in AML programs, where machine learning, graph analytics, and generative AI fit, what regulators and examiners expect, and why governance, validation, and human review matter as much as model performance.
- AI Transaction Monitoring
- AML Monitoring
- Suspicious Activity Reports
- Model Risk Management
- Alert Prioritization
- Financial Crime Compliance
AI transaction monitoring uses machine learning, network analytics, and generative AI to detect, score, and prioritize account activity that may need anti-money laundering (AML) review. In most US banks, it runs alongside rule-based scenarios rather than replacing them.
Anyone who has run an AML program knows the core tension. Most alerts never become a Suspicious Activity Report (SAR), yet every alert needs a documented decision. AI promises to lighten that load. A model you can’t explain or validate, however, becomes an exam finding of its own.
AI monitoring is one branch of the broader field of AI fraud detection and financial crime compliance. It shares data with real-time fraud systems, but it does a different job. Fraud tools try to stop a loss at the moment of payment. AML monitoring asks whether activity, viewed over time, looks like money laundering or other financial crime that must be reported.
This guide explains how a transaction monitoring system works and where AI fits. It also shows how investigations change, what governance examiners expect, where the technology falls short, and how to judge the business case.
Key takeaways
- AI usually augments rules. Most deployments score and prioritize rule-generated alerts rather than replacing scenarios outright.
- Data limits results more than models do. Entity resolution and a unified customer view often matter more than algorithm choice.
- AML models are harder to train than fraud models. A SAR records suspicion, not a confirmed crime, so the labels models learn from are weak.
- Governance decides whether AI survives an exam. Expect to show validation, documentation, explainability, and evidence of human review.
Table of Contents
What Is AI Transaction Monitoring?
AI transaction monitoring is the use of machine learning, network analytics, and generative AI to find and rank potentially suspicious financial activity for AML investigation. It typically sits on top of existing rule-based scenarios. Its outputs go to human investigators, who decide whether activity is suspicious and whether to file a SAR.
In AI anti-money laundering programs, “AI” usually means one of three things:
- Machine learning models that segment customers, score alerts, or flag unusual behavior
- Network and graph analytics that link accounts, counterparties, and devices to reveal patterns no single account shows
- Generative AI tools that assemble case context, summarize activity, and draft investigation narratives for human review
Each carries different benefits, risks, and governance needs. Vendors often sell all three under one label, so it pays to ask exactly which one you’re buying.
Where AML Monitoring Ends and Fraud Detection Begins
AML transaction monitoring and banking fraud detection often watch the same transactions, but they answer different questions:
AML vs Fraud · Side-by-Side
AML Transaction Monitoring vs Fraud Detection
Both systems can look at the exact same payment, so it’s easy to mix them up. This comparison shows what each one is built to do, when it acts, and what it learns from.
- 🏦 AML asks: does this look suspicious over time?
- 💳 Fraud asks: should this go through right now?
Category
What we compare
|
AML Transaction Monitoring
Pattern, context, documentation
|
Fraud Detection
Speed and loss prevention
|
|---|---|---|
| Purpose Why it exists | Identify and report suspicious activity Spots activity that may point to money laundering or other financial crime, so your institution can report it to FinCEN. | Prevent losses to the bank and its customers Stops a bad payment, login, or account takeover before money leaves the account. |
| Timing When it acts | Mostly after settlement, often in batch Usually runs daily, weekly, or monthly, because many laundering patterns only show up over several weeks. Batch review | Often before authorization, in real time Scores card authorizations, logins, and outbound payments in milliseconds, while the customer is still waiting. Real time |
| Main output What it produces | Alerts, cases, SAR or no-SAR decisions Every alert needs a documented decision that an examiner or auditor can follow later. | Approve, challenge, or decline A fast call on each event, with step-up checks for the cases that fall in the gray zone. |
| Training labels What models learn from ★ Key difference | SAR decisions, rarely confirmed A SAR records suspicion, not proof. Banks seldom learn what law enforcement found, so models learn from weak labels. ⚠ Weak labels | Chargebacks and confirmed fraud Chargebacks and customer reports usually confirm the loss, which gives models a clearer signal to learn from. Stronger labels |
Bottom line: These systems often watch the same transactions, but they answer different operational questions. Fraud detection decides whether to stop a payment right now. AML monitoring asks whether activity, viewed over time, needs to be reported.
The two meet when fraud proceeds get laundered. An account takeover that moves stolen funds out through mule accounts creates both a fraud loss and a reportable money movement. That’s why you get the most value when both teams share data instead of working in silos.
Fraud prevention is largely about speed. AML monitoring is about pattern, context, and documentation. The two meet when fraud proceeds get laundered. A common example is an account takeover that moves stolen funds out through mule accounts, which creates both a fraud loss and a reportable money movement.
Which Institutions Must Monitor Transactions
The Bank Secrecy Act (BSA) requires covered financial institutions to report suspicious activity to FinCEN. You can’t report what you don’t see, so monitoring is a practical requirement for banks, credit unions, trust companies, broker-dealers, money services businesses, and other covered entities.
Fintechs face a second layer. Most neobanks hold deposits through a sponsor bank, and that bank stays accountable for BSA compliance. Fintechs therefore inherit monitoring expectations through partnership agreements. Federal banking agencies have taken enforcement actions against sponsor banks over BSA/AML oversight of fintech partners, including actions involving Blue Ridge Bank in 2022 and Evolve Bank & Trust in 2024.
New York adds its own rule. NYDFS Part 504 requires covered institutions, including state-chartered banks and trust companies, to maintain risk-based transaction monitoring and filtering programs. A senior officer or the board must also file an annual compliance certification by April 15.
How a Transaction Monitoring System Works
A transaction monitoring system moves activity through a fixed sequence, from raw data to a documented decision. AI can help at most stages, but it rarely owns any of them.
The nine stages are:
- Data intake: Transactions, customer records, and counterparty details load from core and channel systems.
- Entity resolution: Records that belong to the same person or business are linked.
- Risk rating and segmentation: Each customer gets a risk rating and a peer group.
- Scenarios and models: Rules and models evaluate activity.
- Alert generation: Activity that crosses a threshold creates an alert.
- Alert scoring: Alerts are ranked by risk.
- Investigation: Analysts review context and evidence.
- Decision: The bank files a SAR or documents a no-SAR closure.
- Feedback and tuning: Outcomes inform thresholds, scenarios, and models.
Here’s where AI typically contributes, and what stays with people:
AML Monitoring Workflow · AI and Human Roles
The Nine Stages of Transaction Monitoring: Where AI Helps and Who Decides
A transaction monitoring system moves activity from raw data to a documented decision. AI can support most stages, but people stay accountable for the choices that carry regulatory weight.
- 🤖 AI assists: checks, links, scores, and drafts
- 👤 People own: approvals, judgment, and decisions
Stage
Step in the workflow
|
Where AI Can Help
Support, speed, and scale
|
Human Role
Accountability and judgment
|
|---|---|---|
| Stage 01 Data intake Data foundation | Data quality checks Flags missing fields, duplicates, and unusual values as transactions, customer records, and counterparty details load from core and channel systems. | Owns lineage and completeness Confirms every channel feeds the system and that each data point can be traced back to its source. |
| Stage 02 Entity resolution Data foundation | Record matching and network linking Connects records that belong to the same person or business across deposit, wire, ACH, card, and lending systems. | Reviews uncertain matches Settles borderline links, so one customer isn’t split in two and two customers aren’t merged into one. |
| Stage 03 Risk rating and segmentation Data foundation | Behavior-based clustering Builds finer peer groups from how customers actually transact, rather than from product type alone. | Approves methodology Signs off on how ratings and segments are built, so thresholds fit each customer group. Approval gate |
| Stage 04 Scenarios and models Detection | Anomaly detection and pattern scoring Highlights activity that departs from a customer’s own history or peer norms, alongside rule-based scenarios. | Approves scenarios and thresholds Decides which patterns the program watches and where each cutoff sits. Approval gate |
| Stage 05 Alert generation Detection | Model-generated alerts in some setups Some programs let models create alerts directly. Coverage then depends on the model, so the validation bar rises sharply. ⚠ Higher validation bar | Defines coverage Sets what the program must watch, so coverage never quietly shrinks to whatever a model happens to see. |
| Stage 06 Alert scoring Detection | Supervised alert scoring Ranks rule-generated alerts by risk, so investigators work the most urgent cases first. Common starting point | Sets routing policy Decides which scores go to senior investigators, standard review, or streamlined handling. |
| Stage 07 Investigation Review and decision | Context assembly, summaries, draft narratives Pulls the customer profile, account history, and counterparties into one case view, then drafts a summary for review. ⚠ Verify every draft | Judges suspicion Checks the draft against the evidence and decides whether the activity is truly suspicious. |
| Stage 08 Decision Review and decision ★ Human-owned | None by default AI doesn’t make the SAR or no-SAR call. Its earlier work only informs the person who does. | Owns the decision Files a SAR or records a defensible no-SAR closure, with a clear rationale an examiner can follow. Accountable |
| Stage 09 Feedback and tuning Review and decision | Performance and drift monitoring Tracks how models perform over time and flags when customer behavior shifts away from training patterns. | Approves changes Reviews tuning proposals and documents the rationale, approvals, and before-and-after impact. Approval gate |
Bottom line: AI can help at almost every stage, from cleaning data to drafting case narratives. It rarely owns any of them. Approvals, judgments about suspicion, and the final SAR decision stay with trained people.
Rules engines have automated parts of this workflow for decades. What AI changes is how precisely you can separate risky activity from normal activity, and how much investigation prep runs in the background. The accountability still sits with your team.
Automated transaction monitoring has existed for decades in the form of rules engines. What AI changes is how finely the system can separate risky activity from normal activity, and how much of an investigator’s preparation can be handled automatically.
Entity Resolution and the Unified Customer View
Entity resolution is the work of recognizing that several records belong to the same customer or business. It’s often the real bottleneck in AI monitoring.
One customer can appear separately in deposit, wire, ACH, card, lending, and trust or custody systems. Scenarios that each watch a single channel can miss patterns that only appear across products.
Hypothetical scenario: A customer deposits cash at three branches over a week. Within days, funds leave through online banking wires to a new overseas counterparty. The branch cash scenario sees routine deposits. The wire scenario sees a modest transfer. Neither alerts. A resolved customer view that joins both channels shows the full cycle of cash in and wires out.
For many institutions, linking records and counterparties delivers more value than any model upgrade. A model can’t find a pattern spread across records it doesn’t know are connected.
Customer Risk Rating and Segmentation
The customer risk rating links onboarding to monitoring. Customer due diligence (CDD) and enhanced due diligence (EDD) build a risk profile, and that profile decides which thresholds and scenarios apply.
Segmentation groups similar customers so activity is judged against relevant peers. A payroll business, a retiree, a private banking client, and a trust account shouldn’t share thresholds. Traditional programs use broad product-based segments. Machine learning can build finer peer groups from actual behavior, which helps thresholds fit customers more closely.
This step is only as good as the data onboarding captures. Weak KYC and KYB records, especially thin beneficial ownership information, flow straight into weak monitoring.
Batch vs Real-Time Monitoring
Most AML monitoring runs in batches, usually daily, weekly, or monthly, after transactions settle. Many laundering typologies only show up over weeks, so batch review is a sensible design rather than a flaw.
Real-time controls do exist, but they mostly sit in other layers:
- Sanctions screening checks payments against OFAC lists before processing.
- Real-time fraud detection in banking scores card authorizations, logins, and outbound payments in milliseconds.
- Payment controls can hold high-risk transfers for review before release.
Instant payments are blurring the line. The RTP network and the Federal Reserve’s FedNow Service, launched in July 2023, settle payments in seconds, and those payments are generally final. That pushes more risk checks to the moment of payment.
When a vendor promises “real-time AI monitoring,” ask whether it means AML scenarios, fraud scoring, or sanctions screening. Each has a different governance burden and a different value case.
Why Rules-Based Monitoring Generates So Much Noise
Rules-based monitoring produces high volumes of unproductive alerts because static thresholds can’t capture the variety of normal customer behavior. The same rigidity also lets some real risk slip through.
What the “95% False Positive” Figure Does and Doesn’t Tell You
AML false-positive figures of 90% to 95% circulate widely, but most can’t be traced to a dated, published methodology, so they shouldn’t be treated as established fact. High unproductive-alert volumes are a real and widely reported problem. The precise percentage is the weak part.
The figure also hides a definitional problem. In AML, “false positive” usually means the alert didn’t lead to a SAR. That isn’t the same as the alert being wrong. An analyst who reviews genuinely unusual activity and finds a legitimate explanation has done the job correctly.
A low alert-to-SAR rate can point to three very different causes:
- Poor thresholds that fire on normal behavior
- Poor data that misclassifies customers or misses context
- A conservative risk appetite that deliberately casts a wide net
The headline rate can’t tell you which one applies. That’s why alert volume alone is a weak measure of whether AI improved a program.
Where Static Scenarios Break Down
Static scenarios struggle in five predictable ways:
- Generic thresholds: Rules built for retail norms misfire on different customers. A trust account may show infrequent, very large distributions that look alarming by retail standards and are entirely ordinary.
- Single-account logic: Many scenarios evaluate one account at a time. Activity spread across several accounts or newly opened relationships can stay below every individual threshold.
- Fixed lookback windows: A 30-day window misses patterns that unfold over a quarter.
- Overlapping scenarios: Several rules alert on the same activity, which multiplies work without adding insight.
- Stale calibration: Thresholds set years ago may no longer reflect today’s customers, products, or channels.
Hypothetical scenario: A trust account makes two large distributions in a quarter to a newly formed LLC with layered ownership. A retail-calibrated rule alerts on the amount, which is the wrong signal. It ignores the counterparty’s opacity, which is the right one. Better segmentation and beneficial ownership data would fix both problems.
Cutting alert volume without creating blind spots is its own discipline. It depends on careful segmentation, above- and below-the-line testing, and documented tuning decisions, not on switching off noisy rules.
Rules, Machine Learning, and Generative AI: Where Each Fits
Rules, machine learning, and generative AI each solve a different part of the monitoring problem. Mature programs use all three, with clear limits on what each is allowed to decide.
AML Detection Methods · Side-by-Side
Rules vs Machine Learning vs Generative AI in AML Monitoring
Each approach solves a different part of the monitoring problem. This comparison shows what each one does well, where it falls short, and how much governance it brings with it.
- 📏 Rules: watch for known patterns
- 🧠 Machine learning: rank and find the unusual
- ✍️ Generative AI: prepare the case file
Category
What we compare
|
Rules and Scenarios
Defined patterns, fixed thresholds
|
Machine Learning
Scoring, segments, anomalies
|
Generative and Agentic AI
Context, summaries, drafts
|
|---|---|---|---|
| Main job What it’s built to do | Generate alerts on defined patterns Fires when activity crosses a set threshold, such as cash deposits just under reporting limits. | Segment, score, prioritize, find anomalies Groups customers by real behavior, ranks alerts by risk, and flags activity that departs from the norm. | Assemble context, summarize, draft narratives Pulls case data into one view and writes a first draft for the investigator to check and edit. |
| Key strength Where it adds value | Transparent and familiar to examiners Anyone can see why an alert fired, which makes coverage easy to explain and test. | Finds complex, cross-account patterns Surfaces mule networks and layered activity that single-account rules tend to miss. | Saves investigator time on documentation Cuts the hours spent gathering data and writing case notes, so analysts can focus on judgment. |
| Key weakness Where it falls short | Noisy, rigid, single-account logic Static thresholds misfire on normal customers and let activity spread across accounts slip through. ⚠ High alert noise | Weak labels, explainability, drift Learns from SAR decisions rather than confirmed crime, and loses accuracy as behavior changes. ⚠ Weak labels | Hallucination, unclear validation scope Can state facts that aren’t in the data or leave key transactions out of a summary. ⚠ Verify every draft |
| Governance burden What examiners expect ★ Exam focus | Tuning rationale and documentation Every threshold change needs a recorded reason, approval, and before-and-after impact. Established | Full model risk management Expects sound development, independent validation, and ongoing monitoring under SR 11-7 principles. Heaviest load | Proportionate controls, scope still debated Whether these tools count as models is unsettled. Testing, logging, and human review apply either way. Still evolving |
| Typical role Where it sits in the program | Baseline coverage The approved foundation that defines what the program must watch. | Layer on top of rules Most often scores and prioritizes rule-generated alerts rather than replacing scenarios outright. | Investigator support; a human decides Prepares the case. A trained investigator still judges suspicion and owns the SAR decision. Human in the loop |
Bottom line: Mature programs use all three, but with clear limits on what each is allowed to decide. Rules set baseline coverage, machine learning sharpens where investigators spend their time, and generative AI speeds up case preparation.
None of them replaces human judgment on suspicion or the final SAR call. Define each tool’s decision rights up front, document them, and you’ll have a program you can explain to an examiner.
Alert Generation vs Alert Prioritization
The most important question to ask about any AI monitoring tool is whether it generates alerts or prioritizes them.
- Alert generation: A model creates alerts directly, sometimes replacing a scenario. Coverage now depends on the model, and the burden of proof rises sharply.
- Alert prioritization: A model scores alerts that rules already produced, so investigators work the riskiest cases first. Every alert is still handled under policy, and coverage stays anchored to approved scenarios.
Prioritization is the more common starting point, and it’s easier to govern. It changes where investigator time goes without changing what the program covers. Generation can surface patterns rules never would, but it demands stronger validation and a clear account for examiners of what the model watches and what it doesn’t.
Machine Learning Methods Used in AML
Machine learning AML programs typically draw on four method families:
- Segmentation and clustering: Groups customers by actual behavior rather than product type. Better peer groups mean more relevant thresholds.
- Unsupervised anomaly detection: Flags activity that departs from a customer’s history or peer norms. It needs no labels, but unusual isn’t the same as suspicious.
- Supervised alert scoring: Learns from past alert outcomes to estimate which new alerts are most likely to be escalated or reported.
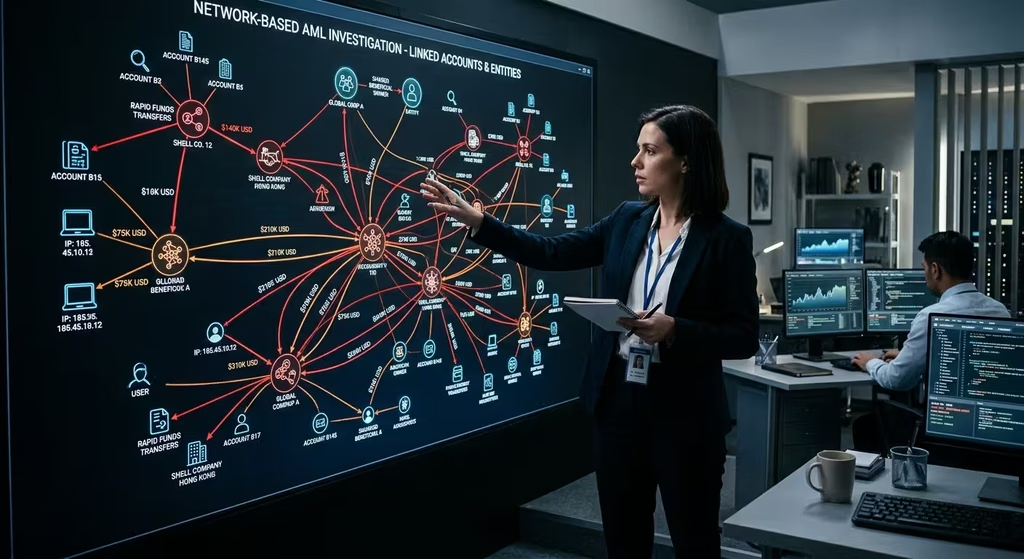
- Graph and network analytics: Maps relationships among accounts, counterparties, devices, and addresses. This is how monitoring surfaces mule networks and layering that single-account views miss.
The underlying mechanics overlap with fraud modeling. Our explainer on how machine learning fraud detection works covers model types, class imbalance, and evaluation in depth. For relationship-based methods, see how graph neural networks detect money laundering.
Hypothetical scenario: Six accounts opened in the past two months share a mailing address and a device. Each receives several incoming transfers, then sends the funds onward within a day. Individually, each account looks unremarkable. As a network, they show the rapid in-and-out movement typical of money mule activity.
Why AML Models Are Harder to Train Than Fraud Models
AML models are harder to train because the labels they learn from are weaker. In card fraud, a chargeback or customer report usually confirms that fraud happened. In AML, the closest label is a SAR decision, which records suspicion, not proof.
Three more problems compound this:
- Outcomes rarely come back. Banks seldom learn whether law enforcement acted on a SAR or what it found.
- Reportable activity is rare. Severe class imbalance makes it easy for misleading metrics to flatter a weak model.
- Typologies change. Criminals adapt, so historical patterns lose value over time.
A model trained on past SAR decisions learns what your investigators found suspicious. It doesn’t learn what was actually criminal, and it can repeat your program’s past blind spots. That’s why supervised “detection” claims deserve scrutiny, and why prioritization dominates real deployments.
Key point: Treat any AML model’s performance figures as relative to your institution’s own historical decisions, not to ground truth.
Inside an AI-Assisted Alert Investigation
Generative and agentic AI tools now handle much of an investigator’s preparation work. Some vendors describe their tools completing an investigation in seconds. Those timings are vendor-specific and vary with each system and its data. The measures that matter to a bank are analyst time per alert and decision quality, not model latency.
Hypothetical walkthrough of an AI-assisted review:
- Context assembly: The tool gathers the customer profile, risk rating, account history, counterparties, prior alerts and SARs, and any adverse media hits.
- Hypothesis and scoring: It identifies which typologies the activity resembles, such as structuring or rapid movement of funds, and how strongly.
- Evidence summary: It drafts a narrative citing the specific transactions and data points behind the alert.
- Routing: Based on approved policy, the case is escalated, assigned to a senior investigator, or queued for streamlined review.
- Human decision: An investigator confirms, edits, or rejects the draft and records the final decision with a rationale.
What AI Can Do and What Must Stay Human
AI tools can reasonably handle:
- Pulling data from multiple systems into one case view
- Summarizing account activity over long periods
- Drafting narratives for investigators to edit
- Suggesting relevant typologies
- Searching prior cases for related subjects or counterparties
Some decisions must stay with trained staff:
- Whether activity is suspicious
- Whether to file a SAR
- Approval of any policy that closes alerts with reduced review
Generative AI output carries specific risks. It can state facts that aren’t in the data, leave transactions out of a summary, or use confident language that overstates the evidence. An investigator who signs off on a summary without checking it owns that error.
Hypothetical scenario: An AI narrative summarizes 40 wires but omits two that went to a high-risk jurisdiction. A quality assurance reviewer catches the gap during sampling. Without that check, a no-SAR closure would have rested on an incomplete record.
The Audit Trail an AI Investigation Should Leave
Auditors and independent testers need to reconstruct how every AI-assisted decision was made. A sound trail records:
AI Investigation Governance · Audit Trail
Six Records Every AI-Assisted Investigation Should Leave Behind
When an AI tool helps prepare a case, someone will later need to retrace every step. These six records let an auditor see what the tool used, what it produced, and how your team reached its decision.
- 🧾 Traceability: what the tool saw and ran on
- ✍️ Review: what it wrote and what people changed
- ⚖️ Accountability: who decided, why, and when
Element
Record in the trail
|
Why It Matters
What it proves to an auditor
|
What to Capture
Practical logging detail
|
|---|---|---|
| Record 01 Inputs used Traceability | Shows what data the tool saw and what it didn’t A summary is only as complete as its inputs. Gaps in the data explain gaps in the output. | Sources, date ranges, and exclusions List the accounts, transactions, counterparties, prior alerts, and adverse media the tool pulled, plus anything it couldn’t reach. |
| Record 02 Model and prompt versions Traceability | Ties each output to a specific configuration When a model or prompt changes, results can shift. Versioning lets you explain why two similar cases read differently. | Version IDs and settings in effect Record the model version, prompt template, and key configuration for every case the tool touched. Change control |
| Record 03 Generated output Review | Preserves what the tool actually produced Without the original draft, no one can tell whether an error came from the tool or from the person who edited it. | The unedited draft, stored as-is Keep the first summary, typology suggestions, and narrative exactly as generated, separate from the final version. ⚠ Never overwrite |
| Record 04 Human edits Review ★ Exam focus | Shows investigator judgment, not rubber-stamping Examiners want evidence that a trained person checked the draft against the facts before signing off. | A tracked comparison of draft vs final Log what the investigator added, corrected, or removed, such as wires the summary left out. |
| Record 05 Final decision and rationale Accountability | Documents the basis for SAR or no-SAR A defensible decision lets someone new to the case understand exactly why it went the way it did. | The outcome plus specific reasoning Record the decision, the evidence behind it, and the related accounts reviewed. Skip stock phrases. Human-owned |
| Record 06 Reviewer identity and timestamps Accountability | Establishes accountability Names and times show who owned each step and whether SAR filing deadlines were met. | Who acted, and when, at every step Log the investigator, QA reviewer, and approver, with time stamps for case open, edits, decision, and sign-off. |
Bottom line: Auditors and independent testers need to rebuild how every AI-assisted decision was made, from the data the tool saw to the person who signed off. If any link in that chain is missing, the decision becomes hard to defend.
Strong logging matters as much as model quality. A capable tool with a thin audit trail can still become an exam finding. Build the trail in from day one, and keep tight controls on where confidential SAR data goes.
One more control deserves attention. SAR information is confidential under federal rules. Any generative AI tool that touches case data needs strict controls over where that data goes, who can access it, and whether a vendor can retain it or use it to train shared models.
From Alert to SAR: Making Defensible Decisions
The decision at the end of an investigation is where monitoring meets legal obligation. AI can speed the work that leads to it. It doesn’t change the standard the decision must meet.
Hypothetical structuring case: Over two weeks, a customer makes eight cash deposits between $8,000 and $9,500 at four branches. A scenario flags the pattern. The AI tool assembles the profile: a small retail business with typical monthly cash deposits of about $15,000. The investigator reviews the activity, contacts the relationship manager, and finds no business reason for the change.
Banks must file a Currency Transaction Report for cash transactions over $10,000. Deliberately breaking deposits into smaller amounts to avoid that report is structuring, a federal crime even when the money itself is legitimate. The investigator escalates, and the bank files a SAR.
For banks, SAR rules under 31 CFR 1020.320 generally apply to suspicious transactions involving at least $5,000, with different thresholds for specific situations such as insider abuse.
What a Defensible No-SAR Closure Looks Like
A no-SAR closure is a decision, and it needs the same rigor as a filing. Examiners and auditors look for specific reasoning, not a stock phrase.
SAR Decisions · Closure Quality
Weak vs Defensible No-SAR Closures
Closing an alert without filing is a decision, and examiners review it like one. This comparison shows what separates a closure that holds up from one that turns into a finding.
- ⚠️ Weak: a conclusion with nothing behind it
- ✅ Defensible: specific reasons, evidence, and owners
Category
What examiners check
|
Weak Closure
Hard to defend
|
Defensible Closure
Holds up under review
|
Why It Matters
What a reviewer needs
|
|---|---|---|---|
| Explanation Why it wasn’t suspicious | “Activity consistent with customer profile” A stock phrase that names no facts. It could be pasted into almost any case. ⚠ Stock phrase | “Deposits match seasonal sales; the prior three Decembers show similar volume” Names the actual reason and ties it to the customer’s own history. Specific reasoning | Shows the thinking, not just the verdict A reviewer should see exactly why the activity made sense, in terms of this customer and this pattern. |
| Evidence What backs it up | None attached The reasoning rests on memory or assumption, with nothing an auditor can check. ⚠ Unsupported | Sales records, prior statements, relationship manager notes Each claim in the explanation points to a document in the case file. Documented | Lets reviewers verify, not trust Attached evidence turns an opinion into a finding that an independent tester can confirm. |
| Scope How far the review went | Only the alerted transactions The review stops at the activity that fired the alert and ignores everything around it. ⚠ Narrow view | Related accounts and counterparties as well Checks linked accounts and who the money came from or went to before closing. Full picture | Catches patterns that span accounts Laundering often spreads across several relationships. A single-account review can miss the full cycle. |
| Accountability Who owns the call ★ Exam focus | No reviewer noted Nobody is named, so no one can show who made the decision or whether it was checked. ⚠ No owner | Investigator and QA reviewer identified Names the person who decided and the second reviewer who confirmed the reasoning. Two sets of eyes | Proves the decision had owners Named reviewers show the closure went through quality control, not a quick click to clear a queue. |
Bottom line: A no-SAR closure is still a decision, and it needs the same rigor as a filing. Write it so someone unfamiliar with the case can read it and understand why the activity wasn’t suspicious.
That standard applies whether an investigator or an AI tool drafted the first version. If the reasoning, evidence, scope, and reviewers aren’t on the record, the closure won’t hold up when an examiner asks.
A strong closure lets someone unfamiliar with the case understand why the activity wasn’t suspicious. That standard applies whether a human or an AI tool drafted the first version.
SAR Timelines and Continuing Activity
Under FinCEN rules, banks generally must file a SAR within 30 calendar days of initially detecting facts that may support a filing. If no suspect has been identified, filing may be delayed up to an additional 30 days, for a maximum of 60 days.
Suspicious activity that continues after a filing raises its own reporting questions, and FinCEN’s SAR FAQs address how institutions handle continuing activity. Many banks have built internal procedures around a 90-day review cycle. The sound approach is to tie internal policy directly to FinCEN’s published FAQs and document the reasoning, rather than relying on inherited habit.
These deadlines are where AI speed earns its value. Alert backlogs compress investigation time and push teams toward filing windows. Faster case preparation helps only if it gives investigators more time for judgment, not less.
Model Risk Management for AI Monitoring
Model risk management is where AI monitoring programs most often succeed or fail in an exam. For auditors and AML leaders, this is the part of the program that determines whether a deployment is defensible.
What SR 11-7 and the 2021 Interagency Statement Say
The Federal Reserve’s SR 11-7 guidance on model risk management, issued jointly with OCC Bulletin 2011-12, set the long-standing US framework for model risk. It expects sound development, independent validation, ongoing monitoring, and strong governance. It defines a model broadly as a quantitative method that processes input data into quantitative estimates.
In April 2021, the federal banking agencies issued an interagency statement on model risk management for bank systems supporting BSA/AML compliance. It explained how those principles apply to monitoring:
- It didn’t create new BSA/AML requirements.
- Not every BSA/AML system is automatically a model. That depends on the system’s characteristics.
- Where a system is a model, the principles apply flexibly and in proportion to risk.
The practical result is an inventory decision. For each monitoring component, including every scenario engine, scoring model, and AI tool, the institution should document whether it’s treated as a model and why.
Are Generative and Agentic AI Tools “Models”?
Whether generative and agentic AI tools fall within model risk management scope is an open governance question, not settled law.
- The case for treating them as models: Their outputs shape suspicious activity decisions. A biased or incomplete summary can drive a wrong outcome.
- The case for treating them as tools: A large language model writing a narrative doesn’t produce a quantitative estimate in the SR 11-7 sense.
The defensible position doesn’t depend on the label. Apply controls in proportion to the risk: testing, performance monitoring, access controls, documentation, and mandatory human review. The NIST AI Risk Management Framework and its Generative AI Profile (NIST AI 600-1) offer voluntary structures for those controls.
Supervisory thinking on AI keeps evolving. Write model risk policies so they can absorb new expectations, and assign a named owner for tracking agency guidance on AI.
Validation Methods That Hold Up in an Exam
Validating an AML model means showing it works as intended without quietly reducing coverage. Methods that hold up include:
- Parallel runs: The new model operates alongside existing rules, and results are compared before go-live.
- Above- and below-the-line testing: Analysts sample activity just above and just below thresholds to check whether cutoffs are sensible.
- Back-testing: The model scores historical cases, including past SARs, to show what it would have caught or deprioritized.
- Champion-challenger: A new model runs against the current one on a slice of activity.
- Conceptual soundness review: Validators assess whether the design, data, and assumptions fit the institution’s risk profile.
- Outcome analysis: Ongoing comparison of model outputs with investigation results.
Validators must be independent of the developers. For vendor models, the institution still owns the validation and needs enough vendor documentation to perform it.
What examiners and auditors typically ask for:
Model Risk Management · Exam Evidence Checklist
Seven Evidence Areas to Have Ready for Your AML Model Exam
When an examiner asks how you know your AI monitoring works, your answer lives in your files. This checklist shows what to have ready in each area, why it matters, and where examiners tend to dig deeper.
- 📁 Build evidence: shows how the model was designed and approved
- 🔄 Run evidence: shows it keeps working day to day
Evidence Area
Where it fits
|
What to Have Ready
Documents on file
|
Why It Matters
The risk it covers
|
Examiner Focus
What they test
|
|---|---|---|---|
| Area 01 Inventory Build | Which components are models, and the rationale A full list of scoring engines, segmentation, and AI tools, with the reason each one counts as a model or not. | You can’t govern what you haven’t listed A clear inventory sets the scope for validation, monitoring, and change control. | Complete, current, and justified Examiners check whether borderline tools, like vendor scores or AI summarizers, were assessed rather than skipped. ⚠ Missed components |
| Area 02 Development Build | Data sources, features, and design choices Records of where data comes from, which features drive the model, and why you picked this approach. Data lineage | Design records show the model fits your risks They let a validator trace each output back to sound data and logic. | Data quality and fit for your book Examiners confirm data feeds are complete and design choices match your customers, products, and channels. |
| Area 03 Validation Build ★ Exam focus | Independent validation report, parallel-run and below-the-line results Findings from validators outside the build team, plus side-by-side and threshold testing. Independent validator | Proof the model works without losing coverage Parallel runs and below-the-line sampling show fewer alerts didn’t come from watching less. | Independence and closed findings Examiners look at who validated, what they found, and whether issues were fixed on time. ⚠ Hidden gaps |
| Area 04 Tuning and change control Run | Rationale, approvals, and before-and-after impact A record of every threshold or model change, who signed off, and how it shifted alert volumes. | Changes are where coverage quietly slips Before-and-after numbers show each tweak was deliberate, tested, and approved. | A clean, traceable change trail Examiners want proof that no threshold moved without documented reasons and sign-off. |
| Area 05 Explainability Run | How investigators see the reasons behind a score Screenshots or walkthroughs showing the top drivers an analyst sees on each alert. | Analysts can’t judge what they can’t see Clear reasons help investigators make sound decisions and write defensible narratives. | Plain-language explanations Examiners may ask your team to explain a score in their own words, without leaning on the vendor. |
| Area 06 Ongoing monitoring Run | Performance metrics, drift checks, revalidation schedule Dashboards for alert volumes, conversion rates, and score shifts, with thresholds that trigger review. | Yesterday’s validation can go stale Customer behavior and criminal tactics change, so performance evidence has to keep coming. | Action when the numbers move Examiners look for escalation records showing someone responded when metrics drifted. |
| Area 07 AI-assisted investigations Run Generative AI | Prompt and version logs, human review evidence, QA sampling Records of which model and prompt produced each draft, plus proof an analyst reviewed it. QA sampling | AI drafts still need a human owner Logs let you recreate any output, and QA shows analysts catch errors instead of copying. | Real review, not rubber-stamping Examiners compare drafts with final narratives to see whether analysts actually challenged the AI. ⚠ Rubber-stamping |
Bottom line: Exam readiness isn’t a scramble the week before fieldwork. It’s a file you keep current across all seven areas, so the story of how your model was built, tested, changed, and watched is always ready to share.
Here’s a quick self-check: pick any alert from last quarter and trace it from data source to model version to final decision. If you can do that without gaps, you’re in good shape for the exam.
The FFIEC BSA/AML Examination Manual describes the broader expectations examiners bring to suspicious activity monitoring and reporting.
What US Regulators Expect From AI-Based Monitoring
US regulators have encouraged innovation in AML for years without relaxing any underlying obligation. That two-part message shapes every AI deployment.
Innovation Is Encouraged, Obligations Stay the Same
In December 2018, FinCEN and the federal banking agencies issued a joint statement on innovative efforts to combat money laundering and terrorist financing. It encouraged banks to consider new technologies, including AI. It also indicated that a pilot wouldn’t by itself draw supervisory criticism, even if it exposed gaps in an existing program.
The statement didn’t change BSA requirements. No regulator “approves” a specific AI tool. The institution remains responsible for an effective program, whatever technology it uses.
The Shift Toward Effectiveness-Based AML Programs
The Anti-Money Laundering Act of 2020 pushed US policy toward effective, risk-based programs that produce useful information for law enforcement. FinCEN published its first national AML/CFT priorities in June 2021. In mid-2024, it proposed a rule to modernize AML/CFT program requirements around effectiveness and risk.
The direction of that rulemaking matters more for monitoring than any single provision. It favors programs that can demonstrate useful outputs over sheer alert or filing volume. Well-governed AI prioritization can strengthen that case. Untested automation can undercut it.
State and International Overlays
NYDFS Part 504 remains the most explicit state rule on monitoring, with its program requirements and annual certification. For internationally active institutions, further layers apply:
- FATF has published work on the opportunities and risks of new technologies, including AI, for AML/CFT.
- The Wolfsberg Group has issued guidance on effective monitoring for suspicious activity.
- The EU’s 2024 AML package includes a directly applicable AML Regulation, a new AML Directive, and a regulation creating the Anti-Money Laundering Authority (AMLA).
- The EU AI Act adds obligations for certain AI systems, depending on how each use case is classified.
EU timelines don’t drive US bank obligations, but they shape global programs and vendor roadmaps.
Where AI Transaction Monitoring Falls Short
AI transaction monitoring fails in predictable ways. Knowing them is what separates a defensible program from an expensive one.
- Drift: Customer behavior, products, and channels change, and models trained on old patterns lose accuracy.
- Adaptation: Criminals adjust to the controls they encounter, so last year’s typologies may look different next year.
- Sparse data: New products, low-volume books, and trust and private banking segments may lack enough history to train reliable models.
- Thin or false identities: Monitoring inherits onboarding weaknesses. Synthetic identity theft can hand a model a clean-looking customer who never existed.
- Explainability gaps: Investigators can’t act on a score they don’t understand, and examiners won’t accept one either.
- Feedback loops: Models trained on past SAR decisions repeat past blind spots and can narrow coverage over time.
- Bias in risk ratings: Uneven scrutiny across customer groups creates fair treatment, reputational, and legal risk.
- Automation complacency: Analysts may defer to AI summaries and scores without checking the underlying evidence.
Most of these risks can be managed. None of them is solved by buying a more advanced model.
The Business Case: Cost, Staffing, and Enforcement Exposure
For CFOs, the case for AI monitoring rests on three variables: operating cost, staffing mix, and enforcement exposure.
Cost drivers include investigator headcount, backlog remediation, technology licensing, data engineering, independent validation, and lookbacks ordered after exam findings. AI can lower some of these costs and raise others.
Enforcement exposure dwarfs everything else. In October 2024, TD Bank pleaded guilty to BSA violations and agreed to penalties totaling about $3 billion, according to the Justice Department. The OCC also imposed an asset cap on the bank’s US operations. The government’s account centered on monitoring failures.
According to DOJ, the bank left roughly 92% of its total transaction volume unmonitored between January 2018 and April 2024. No efficiency gain from AI is worth a coverage gap of that kind.
Staffing changes in shape more than size. AI tends to reduce routine first-level review and increase demand for model governance, data engineering, and senior investigation roles.
Hypothetical alert economics: A bank handles 10,000 alerts a month at an average of 30 minutes each. That’s 5,000 investigator hours. At an assumed loaded cost of $75 an hour, it comes to $375,000 a month.
Now suppose a validated scoring model routes 4,000 lower-risk alerts to a streamlined 12-minute review, while 6,000 alerts keep the full 30-minute review. Monthly hours fall to 3,800. That saves 1,200 hours, or about $90,000 a month under these assumptions.
Those savings are real only if coverage holds. Licensing, data work, validation, and ongoing monitoring also belong in the same ledger.
Measuring Program Effectiveness
Alert volume is a poor scorecard. Track several measures together, and know what each one hides:
AML Program Performance · Effectiveness Metrics
Five Metrics That Show Whether Your Monitoring Program Works
Fewer alerts or more SARs can look like progress on a dashboard, but neither one tells the full story. These five metrics help compliance leaders and BSA officers see what each number reveals, where teams usually go wrong, and how to read it with the right context.
- 🛡️ Coverage: are you watching the right risks?
- 🎯 Quality: do alerts lead to useful outcomes?
- ⚙️ Efficiency: can your team keep up?
Metric
What you track
|
Why It Matters
What the number tells you
|
Common Trap
How it gets misread
|
Healthier Approach
How to read it well
|
|---|---|---|---|
| Metric 01 Alert-to-case conversion Quality | Shows whether thresholds are wildly off Higher isn’t always better. A very low rate points to noisy scenarios, while a very high rate can mean thresholds are set too tight. | Chasing the highest ratio and losing coverage Raise thresholds until only obvious cases alert, and the ratio looks great while risky activity slips by unseen. ⚠ Coverage loss | Pair it with below-the-line testing Sample activity just under each threshold, so you can see what a better ratio actually cost you in coverage. |
| Metric 02 SAR filing rate Quality | Useful only with context Some programs should file rarely. A low-risk community bank and a high-risk money services business won’t file at the same rate. | Treating more SARs as automatically better Defensive filing floods law enforcement with low-value reports and buries the ones that actually help. ⚠ Defensive filing | Compare it to your risk profile Read filing trends against your customer mix, and back them up with QA reviews of SAR quality, not just volume. |
| Metric 03 Time to disposition Efficiency | Measures operational efficiency and backlog risk Long queues push cases closer to SAR filing deadlines and leave risky activity waiting for review. | Speeding up reviews by cutting investigative depth Faster closures that skip related accounts or evidence create weak no-SAR decisions that won’t hold up in an exam. ⚠ Shallow reviews | Track speed alongside QA results If review times drop, check that QA pass rates and closure quality hold steady at the same time. |
| Metric 04 Segment-level coverage Coverage ★ Exam focus | Checks whether high-risk customer types are actually watched Confirms that segments flagged in your risk assessment get the monitoring attention they need. | Averaging performance across all customers Strong retail results can hide thin coverage for cash-intensive businesses, MSBs, or correspondent accounts. ⚠ Hidden weak spots | Report by segment, product, and channel Map results back to your risk assessment, so gaps show up in your reporting before an examiner finds them. Risk-mapped |
| Metric 05 Drift indicators Stability | Show when the system starts to weaken Flag when customer behavior, payment channels, or products have changed enough to make models and thresholds less reliable. | Ignoring slow deterioration Overall volumes still look normal, so nobody notices that performance has been sliding for months. ⚠ Silent decay | Set clear review triggers Define the score shifts, conversion changes, or product launches that automatically prompt a closer look. |
Bottom line: No single number proves a monitoring program works. Strong measurement combines coverage, quality, and operating efficiency, so an improvement in one area never quietly hides a loss in another.
That’s why it pays to review these metrics together rather than chase one headline figure. When you can show examiners what you watch, how well alerts convert into useful outcomes, and how your team keeps pace, you have a program you can explain and defend.
For finance leaders, the useful view pairs these metrics with cost per alert and cost per quality SAR. That combination shows whether AI is buying efficiency or just buying fewer alerts.
How to Read Vendor ROI Claims
A claim such as “60% fewer alerts” is the start of a conversation, not a result. Ask:
- What was the baseline? Which scenarios, thresholds, and alert volumes?
- Over what period? A single quarter can reflect seasonality.
- In which segment? Retail results may not transfer to trust or commercial books.
- How was it validated? Parallel run, back-test, or vendor estimate?
- Who measured it? The vendor, the client, or an independent validator?
- What happened to SAR volume and quality? Fewer alerts alongside fewer quality SARs may mean lost coverage.
If a vendor can’t answer these questions, treat the figure as marketing.
Evaluating or Upgrading a Monitoring System
Choosing a path for AI monitoring comes down to existing infrastructure, data maturity, and governance capacity.
Augment, Replace, or Build
Evaluating or Upgrading a Monitoring System · Decision Path
Augment, Replace, or Build
When you’re ready to bring AI into transaction monitoring, the first big choice is how much of your current setup to keep. Most banks and trust companies start small, while larger institutions with strong data teams may go further. Use this comparison to match each path to your infrastructure, data maturity, and governance capacity.
- 🧩 Augment: add ML scoring to the rules you have
- 🔁 Replace: move to a new platform
- 🏗️ Build: own the system end to end
Path
Your upgrade option
|
Best For
Who it suits
|
Main Benefit
What you gain
|
Main Risk
What to watch
|
|---|---|---|---|
| Path 01 Augment Existing rules with ML scoring Lower lift ★ Common start | Most banks and trust companies A practical fit if your rules engine works and you want investigators to see the riskiest alerts first. | Lower disruption, easier validation Coverage stays anchored to approved scenarios, so you have a simpler story to tell examiners. | Inherits weak data and stale scenarios A scoring layer can’t fix thin customer data or thresholds set years ago. ⚠ Old blind spots |
| Path 02 Replace The platform Heavy lift | Institutions with legacy limits or open findings Worth a look if your current system can’t link channels or keeps showing up in exam reports. | Cleaner architecture and data model You get a fresh start on entity resolution and a unified view of each customer. | Long migration and a heavy parallel-run burden You’ll run old and new systems side by side until results prove coverage holds. ⚠ Long timeline |
| Path 03 Build In-house Highest control | Large banks with data science and MRM capacity A fit only if you already have model builders and a model risk management (MRM) team. MRM team needed | Control and customization You shape every feature, threshold, and explanation around your own customers and risks. | Highest cost and governance load Every validation, drift check, and exam question lands on your team, with no vendor to share it. ⚠ Full ownership |
Bottom line: No single path is right for everyone. Choose based on your existing infrastructure, data maturity, and governance capacity. If your data is fragmented or your MRM team is small, augmenting usually gives you the most reliable return with the least disruption.
Pricing for monitoring platforms is rarely published, so get written quotes. Then add the internal cost of data work, validation, and ongoing monitoring. That’s how you see the true price of each path before you commit.
Pricing for monitoring platforms is rarely published. Vendors commonly quote annual licenses or subscriptions scaled by account or transaction volume, plus implementation fees. Get written quotes, and price in the internal cost of data work, validation, and ongoing monitoring.
A Phased Rollout Examiners Can Follow
A rollout that holds up in an exam leaves a clear record at every stage:
- Scope and inventory: Define what the AI component does and whether it’s treated as a model.
- Data readiness: Confirm coverage of all channels, entity resolution quality, and history length.
- Pilot segment: Start with one customer segment or alert type.
- Parallel run: Compare results against existing rules over a meaningful period.
- Independent validation: Complete and document validation before relying on outputs.
- Documented go-live: Secure approval from the appropriate committee or board, with the rationale recorded.
- Ongoing monitoring: Track performance, drift, and coverage, and schedule revalidation.
Data preparation and validation usually take longer than building or configuring the model.
Questions to ask any vendor:
- Does the tool generate alerts, prioritize them, or both?
- What documentation do you provide to support our independent validation?
- How are scores explained to investigators?
- How do you detect and report model drift?
- Where does our data, including SAR information, reside, and is it used to train shared models?
- What do generative AI features log, including prompts, versions, and outputs?
- What have clients needed to document for their examiners when using this tool?
- What are the full costs, including implementation, data integration, and support?
People Also Ask
What is AML transaction monitoring?
AML transaction monitoring is the ongoing review of customer activity to detect transactions that may need a Suspicious Activity Report. Monitoring should be calibrated to each customer’s risk profile. A trust account and a retail checking account shouldn’t be judged against the same thresholds.
How does AI improve transaction monitoring?
AI mainly improves monitoring by prioritizing alerts, building finer customer segments, and linking activity across accounts and counterparties. It also speeds investigation prep through case summaries. Results depend heavily on data quality, entity resolution, and validation, which is why similar tools perform very differently at different banks.
Do regulators accept AI in AML?
US regulators have encouraged innovation in AML, including AI. But AI tools must still meet BSA obligations and model risk expectations, and no regulator approves a specific product. Expect examiners to ask how a tool was validated and how its outputs are explained and reviewed.
Is AML transaction monitoring real time?
Usually not. Most AML scenarios run in batch after settlement, because many laundering patterns only appear over weeks. Sanctions screening and fraud controls are the main real-time layers. Instant payment rails are changing this, since final payments leave little room for after-the-fact intervention on outbound funds.
Can AI replace AML analysts?
No. AI can gather data, summarize activity, and draft narratives, but deciding whether activity is suspicious and whether to file stays with trained staff. Roles tend to shift toward complex investigations, quality assurance, and oversight of the AI tools themselves.
Can AI automatically close alerts?
Some institutions close certain low-risk alerts with reduced or automated review. That should happen only under validated, documented, and formally approved rules, with ongoing QA sampling of closed alerts. Sampling results should feed back into the policy, so a drift in closure quality triggers review before it becomes an exam finding.
What triggers a suspicious activity report?
An alert alone doesn’t trigger a SAR. The investigation decides. A SAR follows when a bank knows, suspects, or has reason to suspect that activity meets regulatory criteria, such as involving illicit funds or attempting to evade BSA reporting, and the applicable dollar thresholds are met.
How long does an AI monitoring rollout take?
There’s no reliable standard timeline. Data preparation, parallel runs, and independent validation usually take longer than building or configuring the model. Institutions with fragmented channel data or open exam findings should expect a longer path than those with clean, unified data.
The Bottom Line
AI transaction monitoring works best as a layer on sound rules, clean data, and a unified customer view, not as a replacement for them. Its clearest value today lies in prioritizing alerts and preparing investigations, while people keep the decisions that carry legal weight. Fewer unproductive alerts are worth little if coverage shrinks or a model can’t be explained to an examiner. Every AI component, including generative tools, should be something your institution can inventory, validate, explain, and evidence.
Your next step: Map each component of your monitoring program against the examiner evidence table above. Flag every gap, assign an owner, and close it before your next exam or independent test.
AI Transaction Monitoring · Editorial Integrity
Sources & Citations
The regulator guidance, official rules, supervisory materials, public technical references, and internal explainers behind this guide to AI transaction monitoring, AML investigations, alert prioritization, model governance, and suspicious activity reporting.
We built this guide to answer a practical question: how does AI transaction monitoring actually work inside an AML program once you move past vendor language and high-level claims? The article draws on official rules, interagency guidance, supervisory manuals, public technical references, and related internal explainers to show where machine learning, graph analytics, and generative AI fit into transaction monitoring, what investigators still need to do themselves, and what governance examiners expect.
Where the article discusses suspicious activity monitoring, SAR decisions, validation, and examiner expectations, it leans on FinCEN rules, Federal Reserve and OCC model risk guidance, the FFIEC BSA/AML Examination Manual, NYDFS Part 504, NIST AI risk materials, and related public references. Where it discusses relationship-based detection and AI techniques, it also draws on technical materials and Tech Capital Hub’s own explainers on AI fraud detection, fraud scoring models, and graph-based anti-money laundering analytics. This article is general educational information and does not constitute legal, financial, or tax advice.
View full sources, methodology, and editorial notes
This is a practical explainer for operators, compliance teams, fintech readers, and curious beginners who want to understand how AI transaction monitoring works in real AML settings. We used official regulations, supervisory guidance, public technical documentation, standards, and internal explainers where they directly supported the topic.
The article was written to clarify how AML monitoring differs from fraud prevention, why most institutions still anchor programs in rules-based scenarios, where machine learning usually helps most, how graph analytics surfaces linked activity across accounts and counterparties, and why generative AI is better suited to investigation support than final suspicious activity decisions.
We also used governance and supervisory sources to explain validation, inventory decisions, drift monitoring, documentation, model risk management, and the evidence institutions should be prepared to show examiners. Examples marked hypothetical are teaching examples, not live institution data. Public references and vendor materials are illustrative and should not be treated as proof that identical outcomes will hold across every AML program.
- Federal Reserve model risk guidance: Federal Reserve — SR 11-7 Model Risk Management — cited for the core U.S. framework covering model development, validation, monitoring, and governance.
- OCC supervisory model risk guidance: OCC Bulletin 2011-12 — cited alongside SR 11-7 for regulated model governance expectations.
- Interagency BSA/AML model risk statement: Interagency Statement on Model Risk Management for Bank Systems Supporting BSA/AML Compliance — cited for how model risk principles apply to systems used in suspicious activity monitoring.
- FFIEC examination manual: FFIEC BSA/AML Examination Manual — cited for examiner expectations around suspicious activity monitoring, investigation, and reporting.
- FinCEN SAR rule for banks: 31 CFR 1020.320 — cited for suspicious activity reporting obligations and thresholds applicable to banks.
- Federal structuring statute: 31 U.S. Code 5324 — cited for the legal definition of structuring in the article’s teaching example.
- Federal instant payments reference: Federal Reserve Financial Services — FedNow Service — cited for the role of instant payments in shifting some risk checks closer to transaction time.
- NYDFS transaction monitoring rule: NYDFS Part 504 — cited for New York’s explicit rule covering transaction monitoring and filtering program requirements.
- NIST AI governance framework: NIST AI Risk Management Framework — cited for voluntary guidance on managing AI risk, controls, and oversight.
- NIST Generative AI profile: NIST AI 600-1 Generative AI Profile — cited for governance considerations around generative AI tools used in investigative workflows.
- FinCEN and federal agencies innovation statement: Joint Statement on Innovative Efforts to Combat Money Laundering and Terrorist Financing — cited for the regulatory stance encouraging innovation without relaxing underlying BSA obligations.
- FinCEN AML priorities reference: FinCEN National AML/CFT Priorities — cited for the shift toward effectiveness-based AML programs.
- FATF technology and AML/CFT materials: FATF — cited for international context on technology, innovation, and financial crime compliance.
- Wolfsberg Group guidance: The Wolfsberg Group — cited for broader guidance on effective suspicious activity monitoring practices.
- Internal guide to AI fraud systems: Tech Capital Hub — AI Fraud Detection — cited for broader context on where AI fits across fraud and financial crime controls.
- Internal explainer on fraud scores: Tech Capital Hub — Fraud Scoring Models: How a Risk Score Is Built in Milliseconds — cited for score-based decisioning concepts that relate to alert prioritization.
- Internal explainer on graph-based AML detection: Tech Capital Hub — How Graph Neural Networks Detect Money Laundering — cited for linked-entity and network-based detection concepts used in AML monitoring.
- Internal explainer on machine learning fraud models: Tech Capital Hub — Machine Learning Fraud Detection: How the Models Actually Work — cited for background on model types, class imbalance, and evaluation concepts that overlap with AML use cases.
- Internal guide to synthetic identity risk: Tech Capital Hub — Synthetic Identity Theft — cited for onboarding and identity-quality weaknesses that can undermine downstream monitoring.
AI Transaction Monitoring · Editorial Standards
Our Editorial Standards
Tech Capital Hub applies Google’s E-E-A-T framework to every guide on AI fraud detection, AML monitoring, financial crime compliance, and fintech systems, including this one on AI transaction monitoring. We prioritize clear explanations, vendor-neutral analysis, official guidance, and honest trade-offs over hype, vague automation claims, or black-box promises.
In this article, we explain how AI transaction monitoring works inside an AML program: where rules still matter, where machine learning usually adds value, how graph analytics helps surface linked activity, why generative AI is mostly an investigation support layer, and what governance examiners expect before a system can be trusted. Where regulatory or technical precision matters most, we anchor claims to official rules, interagency statements, supervisory manuals, public standards, and recognized technical references.
We also state limits plainly: examples marked hypothetical are teaching examples, legal obligations vary by institution and jurisdiction, and no single model, workflow, or vendor approach works best in every AML environment. This guide is reviewed over time as supervisory expectations, payment rails, and AI governance practices evolve.
View how our editorial standards apply to this article
Built Around Real AML Monitoring Questions
We structured this guide around the questions compliance teams, operators, fintech readers, and curious professionals actually ask. What does AI transaction monitoring do that rules alone do not? Where does alert prioritization help most? What still has to stay with human investigators? When does a model improve workflow, and when does it just add governance burden?
We also focus on the questions that arise once a system is live: how weak SAR labels affect model training, why entity resolution often matters more than algorithm choice, how typologies shift over time, where false comfort can creep into automated summaries, and what evidence an institution should be ready to show examiners. The result is a practical explainer for real operating decisions, not just a high-level definition.
Technical and Regulatory Concepts Explained in Plain English
This article translates core AML monitoring concepts into accessible language without stripping out the important details. That includes rules-based scenarios, supervised alert scoring, anomaly detection, graph analytics, SAR decisioning, model inventory choices, validation, drift, and human review requirements.
We also explain where AML monitoring differs from fraud prevention, why suspicious activity labels are weaker than confirmed fraud outcomes, and why governance matters as much as model performance. Readers do not need a deep background in compliance or machine learning to follow the logic, because each concept is introduced in practical business and operational terms before technical language is layered in.
Official Rules and Supervisory Guidance Where Precision Matters
We support specific claims with official or authoritative sources where accuracy matters most. That includes FinCEN rules and guidance for suspicious activity reporting, SR 11-7 and OCC Bulletin 2011-12 for model risk management, the FFIEC BSA/AML Examination Manual for examiner expectations, NYDFS Part 504 for state-level transaction monitoring requirements, and NIST materials for AI governance.
We also use internal Tech Capital Hub explainers where they add context, including related articles on AI fraud detection, fraud scoring models, machine learning fraud detection, graph neural networks in anti-money laundering, and synthetic identity risk.
Vendor-Neutral, Transparent, and Clear About Limits
This article is written as a vendor-neutral guide. No company paid for placement, and examples are used to explain monitoring design, governance, and workflow trade-offs rather than to claim independent superiority for any product. We also state limits directly: hypothetical scenarios are teaching devices, public references do not replace institution-specific legal review, and supervisory expectations can shift over time.
Where AML monitoring overlaps with reporting obligations, model governance, or automated decision support, we signal clearly that institutions should confirm current requirements with counsel, compliance leadership, and their primary regulator. This article is educational information, not legal, financial, or tax advice.
AI Transaction Monitoring · About the Author
Marcus Delray
Fintech Analyst · Founder of Tech Capital Hub
Marcus Delray is a fintech analyst and the founder of Tech Capital Hub. In this guide, he explains how AI transaction monitoring works in practice, from rules-based scenarios and entity resolution to alert prioritization, suspicious activity investigations, model governance, and examiner expectations. He shows how machine learning, graph analytics, and generative AI fit into AML workflows without treating automation as a substitute for human judgment.
View full author bio, credentials, and links
Marcus Delray has spent more than a decade researching financial technology and explaining how digital systems change the way money moves, risk gets measured, compliance gets executed, and customer decisions are made. He built Tech Capital Hub to make complex fintech topics practical for operators, investors, and curious readers who want clear, useful explanations instead of jargon-heavy summaries.
For this guide, Marcus focuses on the questions that matter most once people move past the phrase “AI in AML.” What does an AI monitoring system actually do beyond rules? Why are suspicious activity labels weaker than confirmed fraud outcomes? Why do governance, validation, and documentation matter as much as model performance? He breaks down transaction monitoring workflows, entity resolution, supervised alert scoring, anomaly detection, graph analytics, suspicious activity reporting, drift, and human review in plain English.
He also explains where AI monitoring falls short: weak labels, sparse data, criminal adaptation, explainability gaps, feedback loops, and automation complacency. Rather than presenting AI as magic, he shows how it fits inside a broader compliance system with rules, investigators, escalation paths, QA review, and ongoing oversight. All articles are educational information, not legal, financial, or tax advice.
- Explains AML monitoring concepts such as rules, alert scoring, entity resolution, model drift, and suspicious activity workflows in plain English
- Covers how AI transaction monitoring fits across bank compliance programs, sponsor-bank oversight, payment risk, and broader financial crime controls
- Compares machine learning, graph analytics, and generative AI approaches without oversimplifying their trade-offs or governance burden
- Shows why validation, explainability, human review, and examiner-ready documentation matter as much as model performance in regulated environments
- Connects technical monitoring design to real operating outcomes, including alert backlogs, investigator workload, SAR quality, and compliance risk
Enjoying our content?
Click below to add us as a preferred source. Google will prioritize our latest articles in your Top Stories, AI Mode, and AI Overviews.
Preferred Source on Google
One thought on “AI Transaction Monitoring for AML: How It Works, Where It Fails, and What Examiners Expect”