Late Payment Prediction Model: How AI Scores Invoice Risk Before It’s Too Late
Fintech Analyst · Founder of Tech Capital Hub
Marcus covers AI in finance, treasury systems, accounts receivable automation, and predictive cash flow strategy in plain English for finance leaders and operators. In this guide, he explains how a late payment prediction model works, what data drives invoice risk scoring, how to measure model accuracy with precision and recall, and how AR teams can act on risk scores before invoices go overdue.
- Late Payment Prediction
- Invoice Risk Scoring
- Accounts Receivable AI
- Precision & Recall
- Model Drift
- AR Automation
Some mornings you open the aging report and already know how the day will go. The same accounts are slipping. The same customers need chasing. You can’t call everyone, so you guess who matters most and hope you guessed right.
That guessing is the real problem. It isn’t a people problem or an effort problem. It’s a visibility problem. A late payment prediction model fixes that. It scores every invoice for risk the moment it’s created, so your team knows exactly where to look first.
If you’re new to how AI fits into accounts receivable, start with our pillar guide on predicting late payments with AI pattern recognition. It covers the big picture. This guide goes one level deeper — how the model works, what data it uses, how to measure it honestly, and how to keep it reliable over time.
No math degree required. Just a willingness to look at your payment data a little differently.
What Is a Late Payment Prediction Model?
Short answer: A late payment prediction model is a machine learning tool that estimates, at invoice creation, how likely each invoice is to be paid late. It learns from historical payment behavior, invoice details, and dispute history, then assigns a risk score so AR teams can act before the due date arrives.
In technical terms, it’s binary classification. The model answers one yes-or-no question: will this invoice be paid late? It doesn’t give you just a yes or no, though. It gives you a probability — say 0.78 — which becomes your AI invoice risk score. That score drives who your collectors contact first, and when.
This is the core idea behind invoice risk scoring: turning passive payment history into a ranked, actionable list before a single invoice goes overdue.
Table of Contents
Risk Scores vs. Payment Date Forecasts
Short answer: A risk score tells you whether an invoice is likely to be late. A payment date forecast tells you when cash will arrive. They answer different questions, use different model types, and should never be judged by the same metrics.
People mix these up constantly. Both use AI. Both look at payment history. But the intent is completely different.
Prediction Model Comparison · AR Context
Risk Scores vs. Payment Date Forecasts
These two models often use similar data, but they solve different problems. One helps collections teams decide who needs attention first. The other helps finance teams estimate when cash will arrive.
- Collections prioritization
- Cash timing visibility
- Right model for the right job
| Dimension | Risk Score | Payment Date Forecast | Best Used For |
|---|---|---|---|
| Core question What each model is trying to answer | Predicts the probability that an invoice will be paid late. It answers a yes-or-no risk question. | Estimates the likely date or timing window when an invoice will be paid. | Use both differently |
| Typical output How the prediction is expressed | A numeric probability or AI invoice risk score, such as 0.78 or 78% likelihood of late payment. | A predicted payment date, expected week, or timing range for settlement. | Action format matters |
| Model family The kind of prediction the model makes | Usually a classification model, often binary classification, focused on whether an invoice is likely to miss terms. | Usually a regression or time-based forecasting model focused on when cash is expected to land. | Different methods |
| Primary business use Who benefits most from the output | Helps AR and collections teams prioritize outreach, set worklists, and act before invoices slip past due. | Helps finance and treasury teams improve cash planning, liquidity visibility, and forecast timing. | Team-specific value |
| Decision timing When the prediction becomes most useful | Most useful at invoice creation or shortly after, so teams can intervene early. | Most useful during rolling cash planning and short-term forecast updates. | Earlier vs later planning |
| Success metrics How performance should be judged | Measured with precision, recall, F1, false positives, false negatives, and confusion matrix performance. | Measured by timing error, date deviation, or broader forecast accuracy methods used in cash forecasting. | Do not mix metrics |
| Best operational action What teams actually do with the result | Route high-risk invoices into a collector worklist, confirm invoice receipt, resolve PO issues, or escalate early. | Update expected cash inflows, refine weekly liquidity assumptions, and improve 13-week planning visibility. | Operational clarity |
| Common mistake Where teams often get confused | Treating a high late-payment probability as if it tells you the exact day cash will arrive. | Assuming a date forecast alone is enough to prioritize collections effort across open invoices. | Avoid overlap |
Use the output that matches the decision. A risk score helps you decide who to act on. A payment date forecast helps you decide what cash timing to expect. When teams confuse the two, they usually measure the model the wrong way and trust it less than they should.
This entire article stays in the left column — classification-based invoice risk scoring. Use a risk score to decide who to call this week. Use a date forecast to decide how much cash you’ll have next month.
If you need the date-forecasting side, our guide to AI cash flow forecasting accuracy metrics covers how payment date and cash forecasts are measured and benchmarked.
The Data Features That Drive Invoice Risk Scores
Short answer: Most of the data you need already exists in your ERP, AR ledger, and CRM. The key is turning raw records into predictive signals — a process called feature engineering.
For example, a list of historical payment dates becomes “average days late over the last six invoices.” That’s a feature your model can actually learn from. Here’s what data is typically used to predict late payments, where it comes from, and why it matters.
Invoice Risk Scoring · Feature Table
The Data Features That Drive Invoice Risk Scores
Compare the strongest inputs behind a late payment prediction model, where they usually live, and why each signal helps predict invoice-level lateness before the due date.
- Behavioral signals
- Source-system quality
- Collections actionability
| Feature | Source System | Why It Predicts Lateness | Signal Strength |
|---|---|---|---|
| Historical days-to-pay Past payment behavior over prior invoices | ERP / AR ledger | Past behavior is usually the strongest single input. Customers who routinely stretch terms often repeat the same pattern unless something changes. | Critical |
| Payment timing drift Slow movement away from normal payment timing | ERP / AR ledger | A customer moving from paying on day 28 to day 36 and then day 44 may be showing early financial strain or a process breakdown. | Critical |
| Dispute frequency How often invoices get challenged or routed for review | CRM / dispute workflow | Frequent disputes create approval delays, pause payment cycles, and often signal recurring operational friction between buyer and seller. | High |
| Invoice amount thresholds Value bands that trigger added review or approval | Billing / ERP | Larger invoices often require extra sign-off. Crossing a buyer’s internal approval threshold can slow payment even when the invoice is otherwise clean. | High |
| Partial or short payments Evidence of deduction behavior or unresolved disagreement | Cash application | Short pays often point to disputes, missing documentation, or customer cash pressure. They are a strong warning sign for future delays. | High |
| Payment terms changes Net-term changes and non-standard arrangements | Customer master / contracts | Changes in terms can shift the baseline for what “normal” looks like and may signal negotiation pressure or higher credit risk. | Medium |
| PO match status Whether purchase-order data aligns cleanly | ERP / procurement data | Missing or mismatched PO details are a common reason invoices get held, disputed, or rerouted before approval. | High |
| Seasonality Recurring timing patterns across months or quarters | Invoice + payment history | Some buyers reliably slow down near fiscal year-end, holidays, or peak operating periods. Seasonality adds context to otherwise normal behavior. | Medium |
| Industry segment Peer behavior by vertical or customer type | CRM / firmographic data | Payment behavior varies by sector. Industry context is especially helpful for newer accounts with limited invoice history. | Medium |
| External credit signals Third-party credit or financial stress indicators | Credit bureau / monitoring feed | External events such as credit deterioration, liens, or adverse filings can reveal rising risk before your own ledger fully shows it. | Medium |
Signal quality beats feature quantity. A premium late payment prediction model does not need dozens of noisy inputs. It needs a smaller set of clean, explainable signals that reflect real payment behavior and support action by collectors.
Not every feature carries equal weight. Historical days-to-pay, payment timing drift, and dispute frequency usually do the heavy lifting. Seasonality and industry segment add useful context. And dirty inputs actively hurt more than they help — a model trained on duplicate customer records or stale dispute flags learns the wrong lessons.
Clean, connected source data is the foundation. Our guide to fixing ERP and AI integration problems covers the most common data issues that break predictive AR models before they get started.
How the Model Is Built
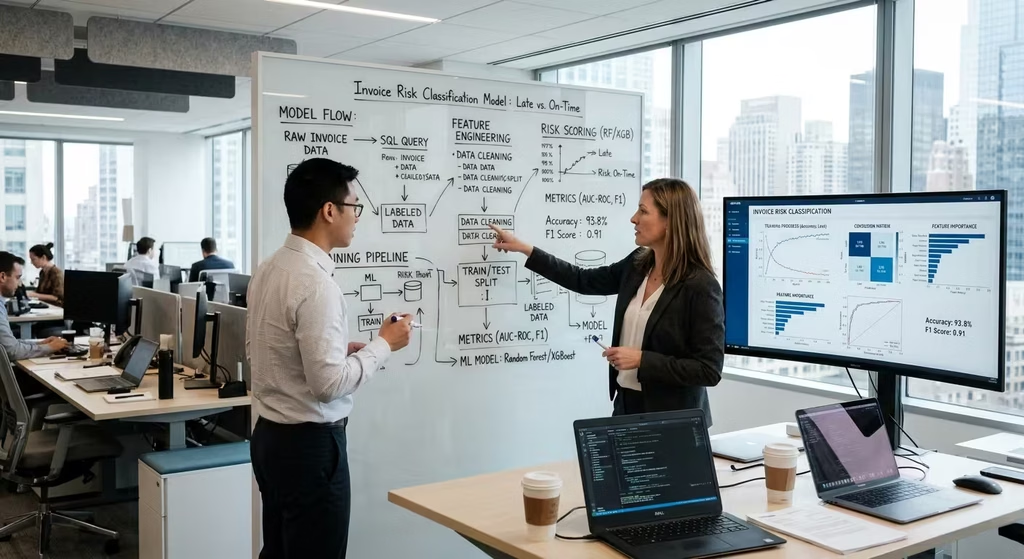
Short answer: Building a payment delay prediction model comes down to three decisions — define what “late” means for your business, choose the right model type, and handle the class imbalance problem so the model doesn’t just predict “on time” for everything.
This is the part that sounds intimidating. It really isn’t.
Step 1: Define What “Late” Means
The model needs a clear target. Every historical invoice must be labeled as “late” or “on time” using a consistent rule. A few common choices:
- Any day past due. Simple, but noisy. A payment one day late because of a weekend clearing delay isn’t a real risk signal.
- More than 15 days past due. A widely used middle ground. It filters out timing quirks without ignoring genuine slow payers.
- More than 30 days past due. Useful when you only want to flag serious delays worth escalating.
Pick the threshold that matches how your team actually works. If you wouldn’t call a customer at five days past due, don’t train the model to flag it. Once every historical invoice carries a label, you have your training data — the foundation the model learns from.
Step 2: Choose a Model Type
There’s no magic algorithm. These are the machine learning models most commonly used for invoice risk scoring, in plain English:
- Logistic regression. The simplest choice. It weighs each feature and combines them into a probability score. Easy to explain, easy to audit. An excellent starting point for any AR team.
- Random forest. Builds hundreds of simple decision trees and lets them vote on each invoice. It handles messy, non-linear patterns well. Think of it as asking a large panel of experienced collectors and going with the majority.
- Gradient boosting. Builds trees one after another, with each new tree correcting the mistakes of the last. It’s often the most accurate option for tabular finance data, though it takes more care to configure and monitor.
Many teams start with logistic regression as a baseline. Then they test gradient boosting or random forest to see if the accuracy gain justifies the added complexity. Sometimes it does. Sometimes the simpler model is enough — and that’s perfectly fine.
Step 3: Handle Class Imbalance
Here’s a trap that catches many teams. In most AR portfolios, only 10% to 20% of invoices are seriously late. That’s good for cash flow. It’s a challenge for the model.
This is class imbalance. When late invoices are rare, a lazy model can predict “on time” for everything and still appear 85% accurate. It’s technically right most of the time. It’s also completely useless for collections.
A few straightforward fixes:
- Class weighting. Tell the model that missing a late invoice is more costly than a false alarm.
- Resampling. Show the model more examples of late invoices during training, or reduce the weight of on-time examples.
- Better metrics. Evaluate on precision, recall, and F1 — not raw accuracy. More on those below.
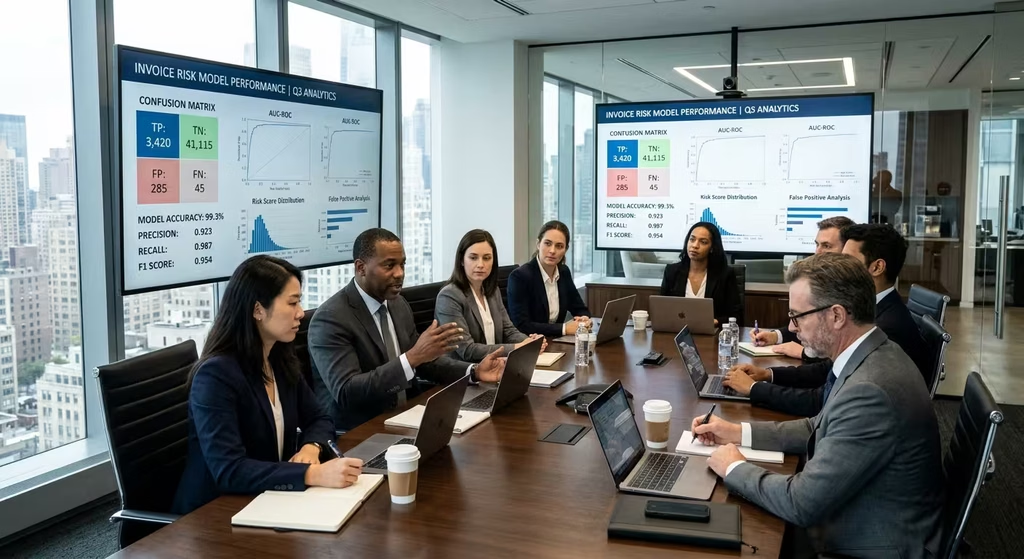
How a Score Becomes an Action
Short answer: A risk score at invoice creation triggers a simple chain — threshold check, worklist routing, early outreach. The collector acts before the due date, not after. That timing difference is where the model earns its keep.
A score sitting in a dashboard collects nothing. Here’s how a working predictive collections model actually turns a score into a collections action.
- Score at creation. The invoice is issued. The model assigns a risk score immediately.
- Threshold check. The score is compared to your risk threshold — say 0.70.
- Worklist routing. Invoices above the threshold appear on a collector’s prioritized list.
- Early action. The collector confirms receipt, verifies the PO number, or sends a friendly check-in before the due date.
- Re-scoring. As new signals arrive — a partial payment, a dispute, a promise-to-pay — the score updates automatically.
These aren’t collection calls. They’re service calls. And customers respond very differently.
How to Set a Risk Score Threshold for Collections
Most teams get this backward. They pick a threshold — often 0.50 — because it sounds logical. Then collectors get buried in low-value outreach.
A better approach starts with capacity. How many proactive touches can your team realistically handle each week?
Say your team manages 60 early calls per week. You issue around 400 invoices per week. That means you can act on roughly the riskiest 15%. Set your threshold at the score level that captures about 60 invoices. Then adjust as you learn.
If collectors finish early, lower the threshold a bit. If they can’t keep up, raise it. Your threshold should match your team’s capacity, not a theoretical default.
How to Measure Risk Score Accuracy
Short answer: Measure precision, recall, and F1 — not overall accuracy. Overall accuracy is misleading for imbalanced datasets. Precision tells you how trustworthy your flags are. Recall tells you how many late invoices you actually caught. F1 balances both into a single comparable score.
This is where most guides lose the thread. Let’s keep it practical.
The Confusion Matrix in Plain English
Every prediction the model makes lands in one of four buckets.
Model Accuracy · Confusion Matrix
The Confusion Matrix in Plain English
Every invoice prediction falls into one of four boxes. This matrix shows whether the model flagged the invoice and whether the invoice actually paid late.
- Predicted outcome
- Actual outcome
- What each result means
| Prediction | Actually Late | Actually On Time |
|---|---|---|
| Flagged as Risky The model predicted late payment risk |
True Positive Caught it correctly The model flagged the invoice, and it did pay late. This is the result you want more of because it helps collectors act early on real risk. |
False Positive False alarm The model flagged the invoice, but it paid on time. This can waste collector effort if it happens too often, though the cost is usually manageable. |
| Not Flagged The model predicted no meaningful risk |
False Negative Missed risk The model did not flag the invoice, but it still paid late. This is often the costliest mistake because the team loses the chance to intervene early. |
True Negative Ignored correctly The model left the invoice alone, and it paid on time. This keeps collectors focused on the accounts that truly need attention. |
Precision and recall both start here. Precision asks how many flagged invoices were truly late. Recall asks how many truly late invoices the model managed to catch. The confusion matrix is the easiest way to see both at once.
That’s it. Four boxes. Precision, recall, and F1 all come directly from them.
Precision, Recall, and F1 — Defined Plainly
- Precision: Of all the invoices flagged as risky, how many were actually late? High precision means collectors spend time on real risks, not false alarms.
- Recall: Of all invoices that actually went late, how many did the model catch? High recall means fewer payment surprises.
- F1: A single score that balances precision and recall. Useful for comparing two models or two threshold settings side by side.
A Worked Example
Your company issues 1,000 invoices in a quarter. 100 end up seriously late.
Your model flags 120 invoices as high-risk. Here’s the breakdown:
- True positives: 75 flagged invoices were genuinely late.
- False positives: 45 flagged invoices paid on time.
- False negatives: 25 late invoices weren’t flagged at all.
- True negatives: 855 invoices correctly not flagged.
The math:
- Precision = 75 ÷ 120 = 62.5%
- Recall = 75 ÷ 100 = 75%
- F1 = 2 × (0.625 × 0.75) ÷ (0.625 + 0.75) = ≈ 68%
Overall accuracy is 93%. That sounds strong. But a model that flagged nothing at all would score 90% — because 90% of invoices are paid on time. Raw accuracy hides the failure. Precision, recall, and F1 reveal it.
Precision vs. Recall: Which One Should You Favor?
You can’t maximize both at once. Lower your threshold and you catch more late invoices — recall rises. But you flag more good invoices too — precision falls.
The right balance depends on the cost of each error:
- A false positive costs a short courtesy call to a customer who would have paid anyway. Mildly inefficient. Rarely harmful.
- A false negative costs real cash. A $40,000 invoice that slips 30 days past due ties up working capital and may trigger a dispute.
For most B2B teams, missing a large late invoice costs far more than one extra phone call. So the practical approach is to favor recall on high-value invoices, accept a few more false positives, and adjust as you watch the worklist in action.
How to Backtest a Model on Your Own Data
Short answer: Use your own invoice history — not a vendor demo — to test a model before you trust it. Split by time, not at random. Score each invoice using only data that existed on its creation date. Then measure precision, recall, and F1 on the holdout period before going live.
Vendor demos look great. Your data tells the truth. Here’s a clean step-by-step process.
- Pull 18 to 24 months of invoice history. Include invoice dates, due dates, actual payment dates, amounts, disputes, and any partial payments.
- Apply your “late” definition consistently. Use the same days-past-due threshold you’ll use in production. Don’t change it mid-test.
- Split by time, not at random. Train on the older months. Keep the most recent three to six months as your holdout set. This mimics reality — you always predict the future using only the past.
- Score each invoice as of its creation date. Use only data that existed on that day. If you include information that arrived later — like a dispute filed two weeks after the invoice — your results will look artificially strong.
- Build the confusion matrix. Compare model predictions against actual payment outcomes in the holdout period.
- Check precision, recall, and F1 by segment. A model can look solid overall and still fail an important customer group. Break results down by invoice size, industry, and account age.
- Test multiple thresholds. Check how precision and recall shift at 0.50, 0.60, and 0.70. Pick the one that fits your team’s outreach capacity.
- Run in parallel. Let the model score live invoices for four to eight weeks while your team works their usual process. Compare results side by side before switching over.
That parallel run builds real trust, fast. It’s the same discipline that matters when you automate a 13-week cash flow forecast with AI. Nobody trusts a black box. People trust something they’ve watched be right for six consecutive weeks.
Scoring New Customers With No History
Short answer: When a customer has no payment history, the model borrows signals from similar customers, external credit data, and invoice-level traits. These cold-start signals carry the most weight early on and fade as the customer builds their own payment record.
This is the cold-start problem, and every AR team hits it eventually. The model can’t learn from behavior that doesn’t exist yet. So it borrows from elsewhere.
Common cold-start signals for customer payment risk scoring:
- Peer cohort behavior. Use payment patterns from similar customers — same industry segment, comparable size, similar region — as a starting baseline.
- External credit data. Credit reports, years in business, payment index scores, and any public filings or liens at onboarding.
- Invoice-level traits. Invoice size, payment terms, and PO match status apply from day one, regardless of history.
- Onboarding quality signals. Did the customer complete the credit application promptly? Did they provide a clear AP process and contact? Friction at onboarding often predicts friction at payment.
- Credit team review. For large first orders, route the new account to a human credit manager before terms are extended.
How Much Weight Should Cold-Start Signals Get?
Treat borrowed signals as a temporary foundation, not a permanent judgment. A simple graduated approach:
- 0 to 2 paid invoices: Lean heavily on cohort behavior and external credit data.
- 3 to 6 paid invoices: Blend cohort data with the customer’s actual payment behavior.
- 7 or more paid invoices: Let the customer’s own history drive the score.
As real behavioral data accumulates, borrowed assumptions should fade out naturally. This keeps your scoring fair to new accounts while still surfacing genuine early warning signs.
Explainability: Why Collectors Need Reason Codes
Short answer: A risk score without an explanation is just a number. Collectors ignore numbers they can’t act on. Reason codes translate model output into plain-language context — what drove the score, and what to do about it.
A score of 0.84 tells a collector nothing useful on its own. A reason code that says “average days late rose from 4 to 22 over the last five invoices” tells them exactly what to bring up on the call.
Examples of useful, action-ready reason codes:
- “Average days late rose from 4 to 19 over the last five invoices.”
- “Invoice exceeds this customer’s typical approval threshold.”
- “Two disputes opened in the last 60 days.”
- “Last two payments were short-paid by more than 10%.”
- “PO number is missing — invoice may be on hold.”
Reason codes come from feature importance analysis. A widely used method is SHAP (SHapley Additive exPlanations), which quantifies how much each feature pushed a specific invoice’s score up or down. You don’t need to understand the math. You just need the output to be readable by someone who hasn’t touched the model.
The practical rule: surface the top two or three reasons per invoice. Use plain language. Tie each reason to a specific action. “Missing PO” tells the collector to confirm the PO number before anything else. That’s a five-minute fix that prevents a 30-day delay.
Reason codes also protect your team during escalations. When a customer pushes back, your collector can point to specific, documented signals instead of saying “the system said so.”
Model Drift and When to Retrain
Short answer: Model drift happens when real-world payment behavior diverges from what the model learned during training. Watch for falling precision or recall, more collector overrides, and threshold shifts. Retrain at least quarterly, and immediately after any major operational change.
Even a well-built model gets stale. Customers change. Markets shift. Your billing process evolves. This gradual decline is model drift — and it’s one of the most common reasons late payment prediction accuracy erodes quietly over time.
Why Late Payment Models Lose Accuracy Over Time
- Customer behavior changes. A key account gets acquired and shifts to a new AP process overnight.
- Economic conditions shift. Rising interest rates or a sector downturn change how buyers prioritize payments across the board.
- Internal policy changes. New payment terms, revised dispute workflows, or a billing format change all alter the patterns the model was trained on.
- Data structure changes. An ERP migration renames fields, splits customer records, or introduces gaps the model wasn’t built to handle.
Warning Signs of Drift
Review model performance monthly. Investigate if you see:
- Precision or recall dropping more than a few percentage points from your backtest baseline
- False positives rising to the point where collectors start skipping the worklist
- Recall falling noticeably in a specific industry segment or account tier
- A meaningful shift in the share of invoices crossing your risk threshold
- Collectors manually overriding scores more than usual — a clear signal the model no longer matches their judgment
A Sensible Retraining Cadence
- Monthly monitoring: Track precision, recall, and threshold distribution. Catch drift early.
- Quarterly retraining: Rebuild the model on fresh data as a standing default.
- Event-based retraining: Trigger an immediate rebuild after an ERP migration, a significant credit policy change, or a sharp macro shift.
Don’t retrain just because the calendar says so. Retrain when the performance data says the model no longer fits reality. But don’t skip the calendar checks — they’re how you catch the quiet drift that looks fine until it isn’t.
Governance and Model Risk Controls
Short answer: Good governance means knowing your model works, knowing why it works, and knowing who’s accountable when it doesn’t. It doesn’t have to be heavy. A one-page model card and a monthly performance review cover the basics for most AR teams.
Governance sounds abstract until your CFO asks why a major account got flagged and “the algorithm said so” ends the conversation badly.
Borrow From Proven Frameworks
Banks have managed model risk carefully for years. Their approach translates well even outside regulated finance.
The Federal Reserve’s model risk management supervisory guidance — historically anchored in SR 11-7 principles — emphasizes sound model development, independent validation, and clear governance accountability. Banking regulators have updated model risk guidance recently, so verify the latest supervisory letters if you’re in a regulated institution. The underlying principles — document, validate, review, govern — remain sound for any finance team running a predictive model.
The NIST AI Risk Management Framework offers a broader, voluntary structure built specifically for AI. It’s organized around four functions: Govern, Map, Measure, and Manage. It’s a practical checklist for thinking through reliability, transparency, and human oversight without overengineering the governance layer.
Simple Controls Every AR Team Should Have
- Independent validation. Someone other than the model builder should test it before launch and after every retrain. A second set of eyes catches assumptions the builder missed.
- Clear documentation. Write down your “late” definition, features used, model type, threshold, and backtest results. Keep it in plain English. If a new team member can’t understand it, it’s not clear enough.
- Named ownership. Identify who owns the model, who approves changes, and who reviews monthly performance. Ambiguous ownership means problems get ignored.
- Human override rules. Collectors and credit managers should always be able to override a score — but they should log the reason. Over time, those logs reveal exactly where the model needs recalibration.
- Audit trail. Keep a record of scores assigned, thresholds applied, and actions taken. If a dispute ever arises about how an account was handled, you need to be able to reconstruct the decision.
- Data access controls. Limit who can alter training data or model configuration. Uncontrolled changes make it impossible to diagnose accuracy problems later.
None of this needs to be heavy infrastructure. A well-maintained model card, a shared performance log, and a monthly 30-minute review meeting get you most of the way there.
The Bottom Line
A late payment prediction model isn’t magic. It’s a simple idea executed carefully. Learn from your payment history. Score every invoice at creation, anchored to classification-based invoice risk — not date forecasting, not software selection. Act on the riskiest invoices first. Measure honestly with precision, recall, and F1. And keep the model fresh as your business and customers evolve.
This isn’t about replacing your collectors. It’s about giving them a better starting list every morning. Less guessing. Fewer surprises. More time spent on the accounts that genuinely need a human conversation.
Start with clean data. Write down a clear definition of late. Backtest on your own history before trusting any vendor. And keep the reason codes readable enough that a collector can act on them in thirty seconds.
That’s the whole recipe. It’s less complicated than it looks — and it pays for itself faster than most AR teams expect.
People Also Ask
How does AI score invoice risk?
AI scores invoice risk by learning from historical invoices that were paid late or on time. It analyzes features like historical days-to-pay, dispute frequency, invoice amount, and payment terms. When a new invoice is created, the model compares it to those learned patterns and outputs a probability of late payment — the invoice’s risk score.
What data is used to predict late payments?
Most invoice risk scoring models draw from AR ledger data, payment history, dispute records, invoice amounts, payment terms, PO match status, and seasonal patterns. Many also incorporate industry segment and external credit signals. The strongest predictors are almost always the customer’s own historical payment behavior and any recent shifts in that behavior.
What is the difference between a late payment risk score and a payment date forecast?
A risk score predicts whether an invoice will be paid late. It’s a classification output — a probability between 0 and 1. A payment date forecast predicts when a specific invoice will be paid. They serve different purposes, use different model types, and are measured differently. Risk scores are judged by precision, recall, and F1. Date forecasts are judged by error in days.
How do you measure late payment prediction accuracy?
Use precision, recall, and F1 rather than overall accuracy. Overall accuracy is misleading on imbalanced datasets where most invoices pay on time. Precision shows how many flagged invoices were genuinely late. Recall shows what share of all late invoices the model caught. F1 balances the two. Use a confusion matrix to visualize true positives, false positives, false negatives, and true negatives clearly.
What’s the difference between precision and recall for late payment prediction?
Precision measures how trustworthy your high-risk flags are. Recall measures how many actual late invoices you caught before they were due. Improving one typically reduces the other. Most B2B AR teams prioritize recall on high-value invoices, because missing a large late payment costs significantly more than one extra proactive call.
How do you set a risk score threshold for collections?
Start with your team’s outreach capacity. Determine how many proactive contacts your collectors can handle each week. Set the threshold at the score level that generates roughly that many flagged invoices. Then adjust based on real results — lower the threshold if capacity allows, raise it if the worklist becomes unmanageable.
How does AI score new customers with no payment history?
It uses cold-start signals: peer cohort behavior from similar customers, external credit data, invoice-level traits like amount and payment terms, and onboarding quality signals. As the customer builds their own payment record — typically after six or more paid invoices — the model shifts weight progressively toward their actual behavior.
Why do late payment prediction models lose accuracy over time?
Model drift. Customer behavior changes, economic conditions shift, and internal billing processes evolve. All of these alter the patterns the model was trained on. Monitor precision and recall monthly. Retrain at least quarterly, and immediately after any major change — ERP migration, new credit policy, or significant market disruption.
What machine learning models are used for invoice risk scoring?
The most common are logistic regression, random forest, and gradient boosting. Logistic regression is the simplest and most explainable — a good starting point for most teams. Random forest and gradient boosting handle more complex, non-linear patterns and often improve accuracy, but require more careful monitoring. Start simple and add complexity only when the data justifies it.
Late Payment Prediction Model · Editorial Integrity
Sources & Citations
The official frameworks, internal references, and authoritative documentation behind this guide to late payment prediction models, invoice risk scoring, model accuracy, explainability, and governance.
This guide was built to explain classification-based invoice risk scoring clearly and responsibly. Core governance references rely on official frameworks such as the NIST AI Risk Management Framework and Federal Reserve model risk guidance. Internal references were used where they directly support adjacent concepts like AR prediction, cash flow forecast accuracy, and operational deployment. Because model governance expectations, financial documentation, and implementation practices evolve, always confirm the latest requirements and source materials before applying them in production.
View full sources, methodology, and editorial notes
This guide was written using primary and authoritative sources wherever possible. Preference was given to official AI governance frameworks, financial supervisory guidance, and internal Tech Capital Hub articles that directly support the surrounding topic cluster. These sources were used to explain how a late payment prediction model works, how invoice risk scoring differs from payment date forecasting, how to interpret precision and recall, why confusion matrices matter, and how to think about model drift, retraining cadence, and explainability. Where regulatory or framework references are broader than accounts receivable specifically, they are used to ground governance concepts rather than to imply direct legal requirements for every business. This article is educational information, not financial, legal, or compliance advice.
- Official AI governance framework for trustworthy model design and monitoring: NIST — AI Risk Management Framework — cited for the Govern, Map, Measure, and Manage framework used to discuss model oversight, transparency, explainability, and ongoing monitoring.
- Federal Reserve supervisory guidance relevant to model risk management concepts: Federal Reserve — Supervision & Regulation Letters — referenced for the supervisory guidance index that includes model risk management materials commonly associated with SR 11-7 concepts such as validation, governance, and independent review.
- Internal pillar article on predictive accounts receivable workflows: Tech Capital Hub — Predicting Late Payments: Using AI Pattern Recognition to Fix Accounts Receivable — cited for broader context on how AI supports AR prioritization, early intervention, and DSO improvement.
- Internal guide to the adjacent forecasting use case: Tech Capital Hub — AI Cash Flow Forecasting Accuracy: Metrics, Benchmarks, and How to Improve It — cited where the article hands off payment-date and forecast-accuracy concepts that sit outside the core intent of invoice risk classification.
- Internal operational guide for downstream forecast deployment: Tech Capital Hub — How to Automate a 13-Week Cash Flow Forecast With AI — cited for practical context on how receivables prediction feeds broader liquidity and forecast operations.
Late Payment Prediction Model · Editorial Standards
Our Editorial Standards
Tech Capital Hub applies Google’s E-E-A-T framework to every guide on AI in finance, accounts receivable automation, and predictive cash flow operations. We prioritize practical explanations, official governance frameworks, financial supervisory guidance, and clearly attributed internal references over hype, vague vendor claims, or unsourced benchmark statements. In this article, governance concepts are grounded in materials such as the NIST AI Risk Management Framework and Federal Reserve model risk guidance. Internal Tech Capital Hub references are used where they directly support adjacent topics like AR prioritization, cash flow forecast accuracy, and forecast operations. Because AI governance expectations, financial workflows, and implementation practices evolve, examples and references are reviewed over time rather than treated as permanently fixed.
View how our editorial standards apply to this article
Built Around Real Finance-Team Questions
This article is structured around the way AR, credit, and finance teams actually evaluate a late payment prediction model in practice. Instead of treating AI as a black box, it walks through the concrete questions teams ask first: what data the model uses, how a score differs from a payment date forecast, what a false positive really costs, how precision and recall affect trust, and when model drift becomes a real business issue. The goal is practical decision support, not abstract machine-learning theory.
Technical Concepts Explained in Plain English
Coverage focuses on the mechanics that directly affect invoice risk scoring quality and usability. We explain classification-based prediction, confusion matrices, precision, recall, F1, class imbalance, cold-start scoring, explainability, and retraining cadence without assuming a data-science background. Technical terms are introduced only where they help the reader make a better operational decision, and examples stay tied to real AR workflows instead of drifting into generic AI commentary.
Authoritative Sources Where Accuracy Matters Most
Specific governance and model-risk concepts are anchored to official or authoritative references. The NIST AI Risk Management Framework supports the discussion of trustworthy AI oversight, monitoring, and accountability. Federal Reserve supervisory materials support the model risk management concepts associated with validation, governance, and independent review. Internal Tech Capital Hub articles are cited where they extend the surrounding topic cluster, including AR prediction, cash flow forecast accuracy, and 13-week forecast operations.
Clear About Limits, Use Cases, and Reviewability
We state the limits of predictive finance content as clearly as the mechanics. A model can improve prioritization without guaranteeing collection outcomes. A high accuracy score can still hide costly misses if precision and recall are not understood together. Governance frameworks can guide model oversight, but they do not replace legal or compliance advice for every organization. References, examples, and framework mentions are intended to be reviewable, and readers should confirm current requirements and implementation details before deploying a model in production.
Late Payment Prediction Model · About the Author
Marcus Delray
Fintech Analyst · Founder of Tech Capital Hub
Marcus Delray is a fintech analyst and the founder of Tech Capital Hub. In this guide, he explains how a late payment prediction model works in plain English. He covers invoice risk scoring, the data features that drive late-payment risk, the difference between risk scores and payment date forecasts, and the accuracy metrics finance teams need to judge whether a model is useful in the real world.
View full author bio, credentials, and links
Marcus Delray has spent more than a decade researching financial technology, AI in finance, treasury workflows, and business operating systems. He built Tech Capital Hub to make complex fintech topics practical for finance leaders, operators, and readers who need useful answers rather than vendor jargon. His work covers accounts receivable automation, predictive cash flow systems, forecasting operations, AI governance, and the financial workflows that shape working capital performance.
For this guide, Marcus focuses on a question many finance teams face as AI tools become more common in receivables: what does a late payment prediction model actually do, and how should a business judge whether it is trustworthy? He explains how classification-based invoice risk scoring works, why confusion matrices, precision, and recall matter more than headline accuracy alone, how model drift affects reliability over time, and where explainability and governance fit into deployment decisions. Because this topic touches financial operations, AI oversight, and evolving governance expectations, the article is grounded in authoritative frameworks and clearly attributed supporting references. All articles are educational information, not financial, legal, or compliance advice.
- Explains accounts receivable AI and invoice risk scoring in plain, operational language for finance teams
- Breaks down precision, recall, confusion matrices, class imbalance, and model drift with real-world AR context
- Connects predictive receivables workflows to broader cash flow, treasury, and working capital decisions
- Covers AI governance, explainability, and model oversight with an emphasis on practical business use
- Prioritizes value-first education designed to help readers evaluate tools and risks before deployment
Enjoying our content?
Click below to add us as a preferred source. Google will prioritize our latest articles in your Top Stories, AI Mode, and AI Overviews.
Preferred Source on Google